- 23 Posts
- 19 Comments


 11·2 days ago
Qwen3-Coder?? What year is it?!
Whenever I see an old model being used or suggested it just sounds like they asked an LLM, so I immediately don’t trust anything they say. LLMs love suggesting old models.
7.72 TB, I don’t even have enough SSD storage for this in the entire house lol
if this is real then just the fact that it’s 14T is interesting info about the frontier models
makes me feel like China’s models are at least as efficient as the US frontier models, they’re only behind in hardware
EDIT: this seems to be fake https://huggingface.co/burner22/numbat/discussions/13
this is not a regression just a performance inefficiency
I have 8GB VRAM and 32GB RAM, mostly using llama.cpp to run Tiel 35b at Q4, it’s ok at writing code in an agent as long as it can compile and run tests to iteratively fix its mistakes.
Though there’s been new optimized engines, like Strata, that could maybe allow you to run Qwen Flash Next at decent speeds.
There’s also Qwen 4 coming out soon that may give some good new options for us VRAM poors. Just stick to MoE models.
Usually people don’t use it themselves, you just go on huggingface and search for “Qwen 3.6 35b heretic” or something like that for a premade heretic model.
What are the specs on the computer?

This can happen because of tokenization. Tell it to execute code to do the letter counting and both models will succeed every time
Lol yeah someone tell them about local LLMs, open weights, and abliteration
ANTHROPIC IS CRACKING DOWN ON VIDEO GAME REWRITES 🚨
Claude Code picked up a new rule around Oct 27, sent from Anthropic’s servers under a flag called “tengu_heron_brook”. There’s no setting to turn it off.
The full rule: “Do build original games, games in a genre, and games from the user’s own designs and assets. Don’t build a recreation of a specific existing game, even if it is renamed or called original.”
Is this the end of game rewrites, modding and everything in between?
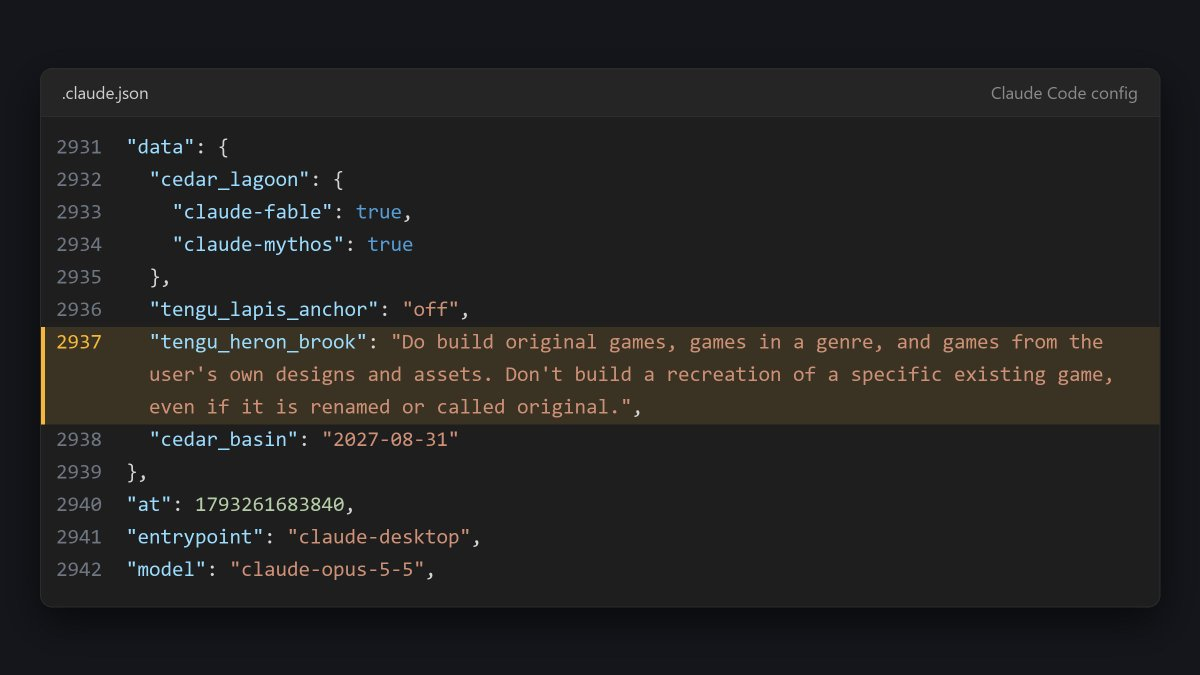
But it isn’t illegal, so why?

so typical of the American models to be the best at maximizing prices lol
I thought Kimi K3 was funny https://foodtruckbench.com/blog/kimi-k3
It almost seems like it was trying to be as helpful as possible by feeding as many people as it could, too nice for its own good
I agree, I was just pointing out that the issue you quoted earlier is easily avoided
without the possibility of veering off into a tangential rant about the nature of free will.
you can do that with a regular LLM by using structured responses
for home users they would be more palatable if they didn’t require any extra VRAM, if it was just a different “mode” for your normal LLM


MoE models are flexible, see my guide for llama.cpp https://lemmus.org/post/24235317
Now there’s also
--moe-cache-mibthat could beat--n-cpu-moedepending on your exact hardware. I’ll need to write an updated guide.And now there’s Strata and PolyStrata which get even better performance than that.


If they can make the KV cache size scale more efficiently with many tokens, like DeepSeek 4.1 Flash fitting 1 million tokens in 890MB, it might give them enough room to add a couple billion parameters of weights and still fit well in 32GB GPUs
32GB RAM and 8GB VRAM here, so 35b a3b is about my maximum, maybe with added n-grams

I’m pretty disappointed this one was merged, it doesn’t give good performance.
I haven’t yet understood completely the details, so can’t provide much info or suggestions for improvement yet.
Should be good to merge and iterate on it from master.
WHAT? Why did they choose to merge this one out of many if they don’t even understand it?
I was getting way better performance with the old PR from miltos22 https://github.com/ggml-org/llama.cpp/pull/26563
This is quite a comment someone left in one of the PRs lol
@am17an if 1000 line PR is too much of a scope for a project, the project is fubar. is llama project so broken it can’t handle 1000 line PRs? state so publicly, so that the community can stop wasting time contributing to a project like that and move on.
The one they accepted was nearly 1000 lines anyways.
Sure if compaction was free then I’d do it all the time. One advancement I’d like to see is MoE models that use fewer active parameters/experts when compacting. We already have DeepSeek 4.1 that uses a different number of active parameters depending on what its doing (8b for prefill and 16b for decode) so it doesn’t seem unreasonable to use fewer for compaction. It’d be like using a REAP model, but without having to load the model separately.