
4·
1 day agoYeah, colon perforation is not a fun way to die.
Avid PC gamer, Linux convert, SCP fan.
Love Science Fiction, Cyberpunk, post-apocalyptic settings; Fan of the games of the defunct Arkane Studios. Listening to (Power-, Speed-, Thrash-)Metal, Gothic, Deathrock, EBM, Vaporwave, Lo-Fi; Classic and Musicals are fine too. Can’t stand Hip-Hop.
Owned by two cats, recently divorced, blessed with a personality disorder (AVPD) - pensioned (even the state has the opinion I’m a total wreck lol). This causes me to be unable to keep up personal connections and makes me ghost literally everyone, so if it happens to you, sorry in advance.
Chronically online.
Pro GenAI, but Anti-GenAI-Corpos; this technology should be available to everyone, which would only be fair since we all contributed to it. Datasets and Models should be under the jurisdiction of UNESCO, since they are literally the distilled cultural output of humanity.
Yeah, colon perforation is not a fun way to die.

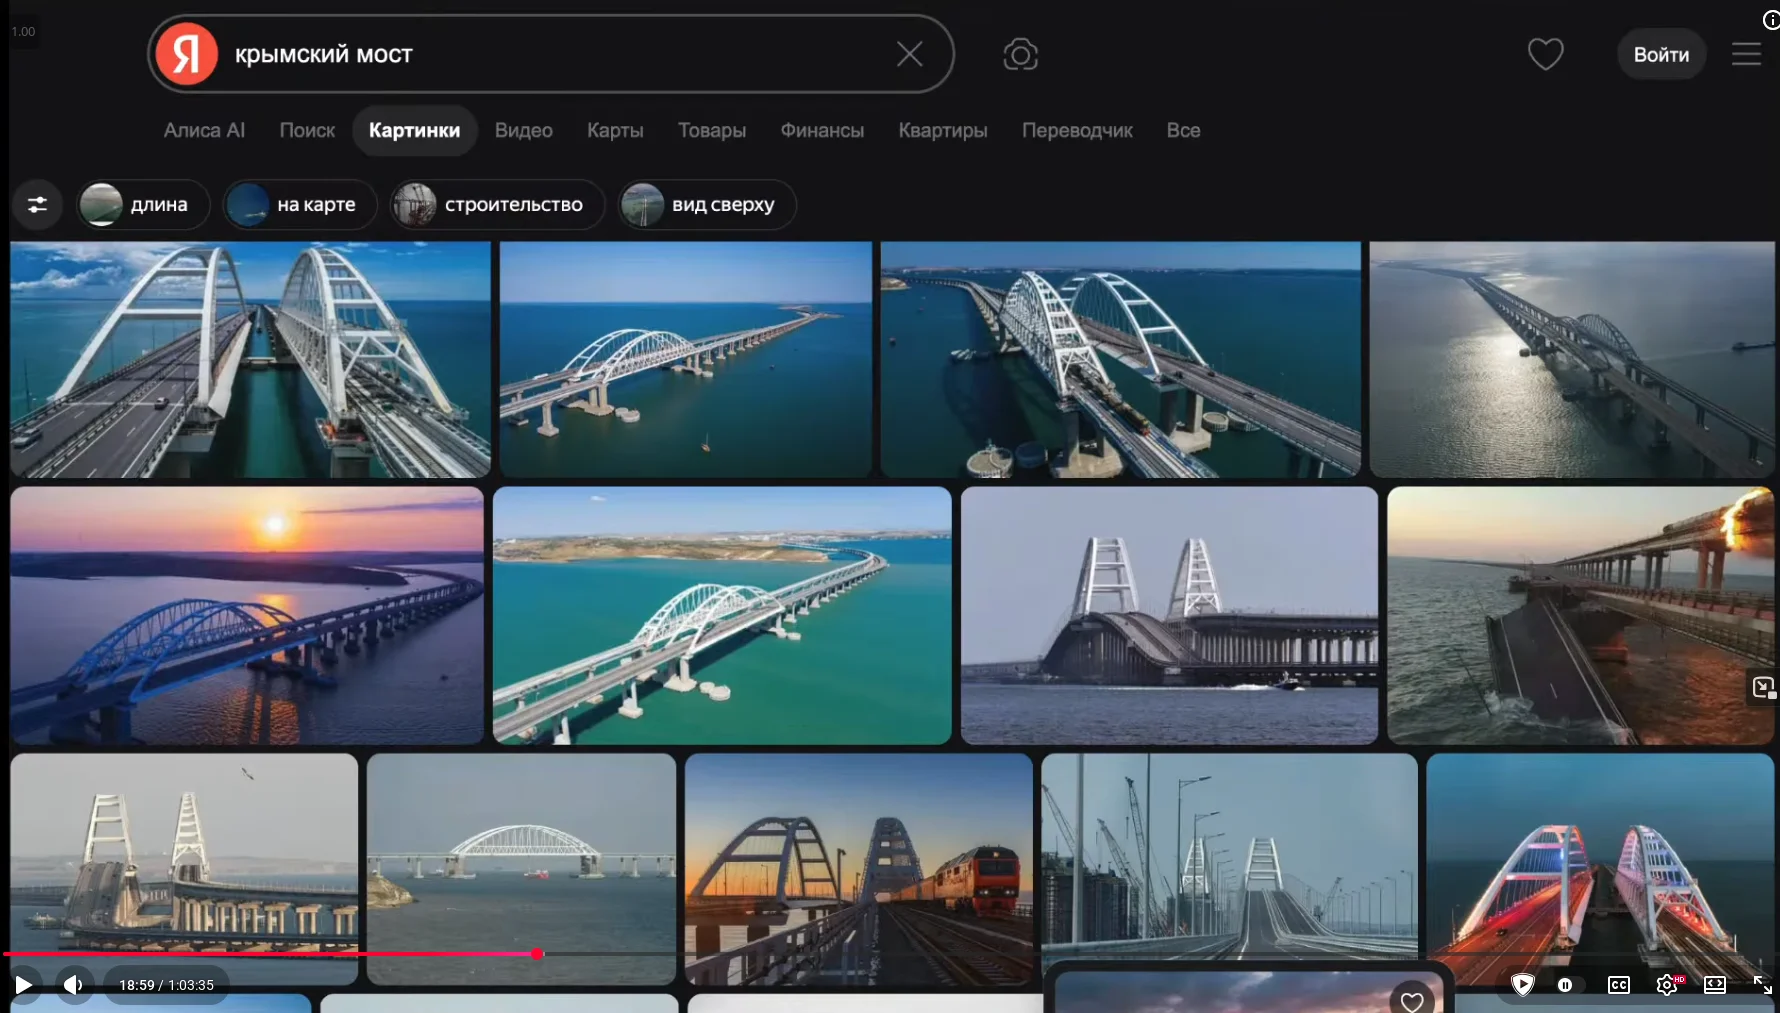
I’ll put this into a reply. This is the image search for the Kerch Bridge on Yandex:
This is the Google result:
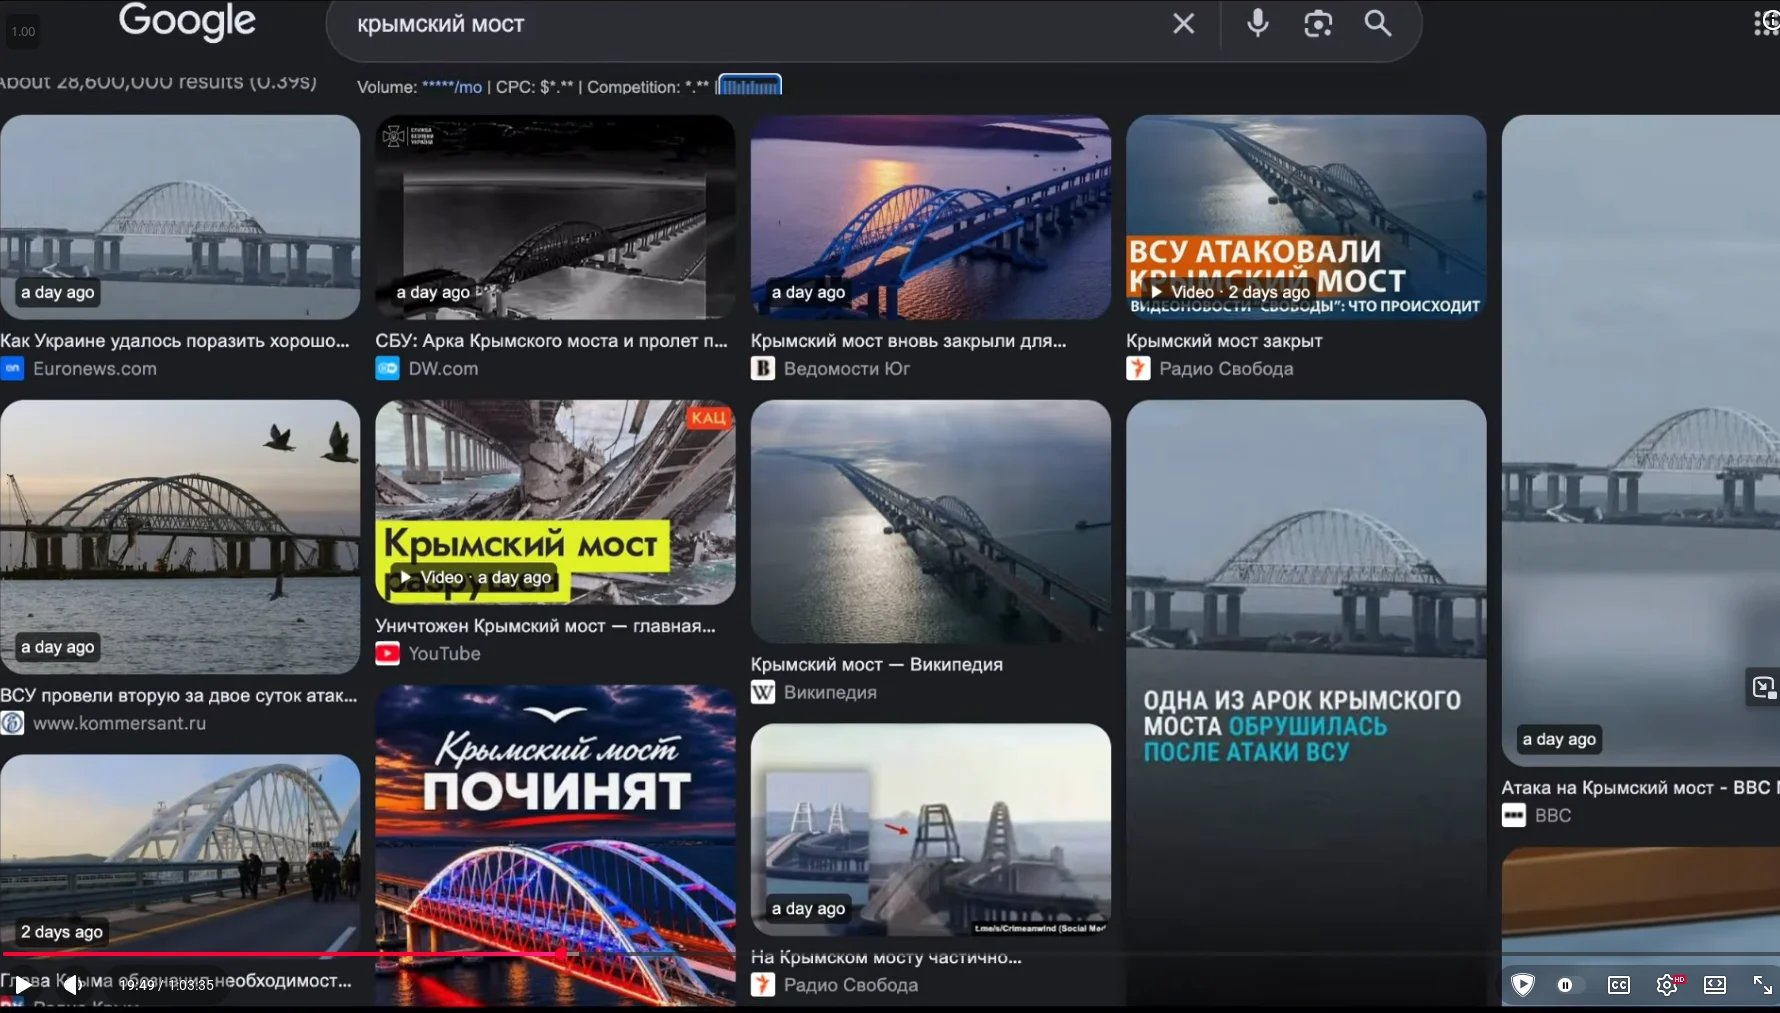
There are no pictures of the destroyed bridge on Yandex.

A fully staffed CISA would probably not prevented all of the stuff happening, but the reaction would be much swifter, outages wouldn’t last as long and sensitive data would be a lot less exposed. Noone is safe in this current LLM fueled frenzy unearthing decade old bugs, but how heavy the impact of this situation is is very much dependent on the ressources orgs like CISA have at their fingertips.
Don’t dismiss that through the power of propaganda and being cut off from outside sources, these people do not even know that they will be doing evil things.
Edit: Sure, downvote me, but this doesn’t change the fact that this part of the russian population still has still no fucking clue. These are people who do not have contact with outsiders, and the war has not arrived in their immediate surroundings. They are mostly not so well educated country people. If you look at the top web portals in Russia, there was no real mention of the collapse of Kerch Bridge on their landing page - the news there focused on how much Kyiv suffers from the ballistic strikes, not on the destroyed crown jewel of fucking Putin.
This is the main page of Lenta.ru, one of the most visited news sites in Russia.
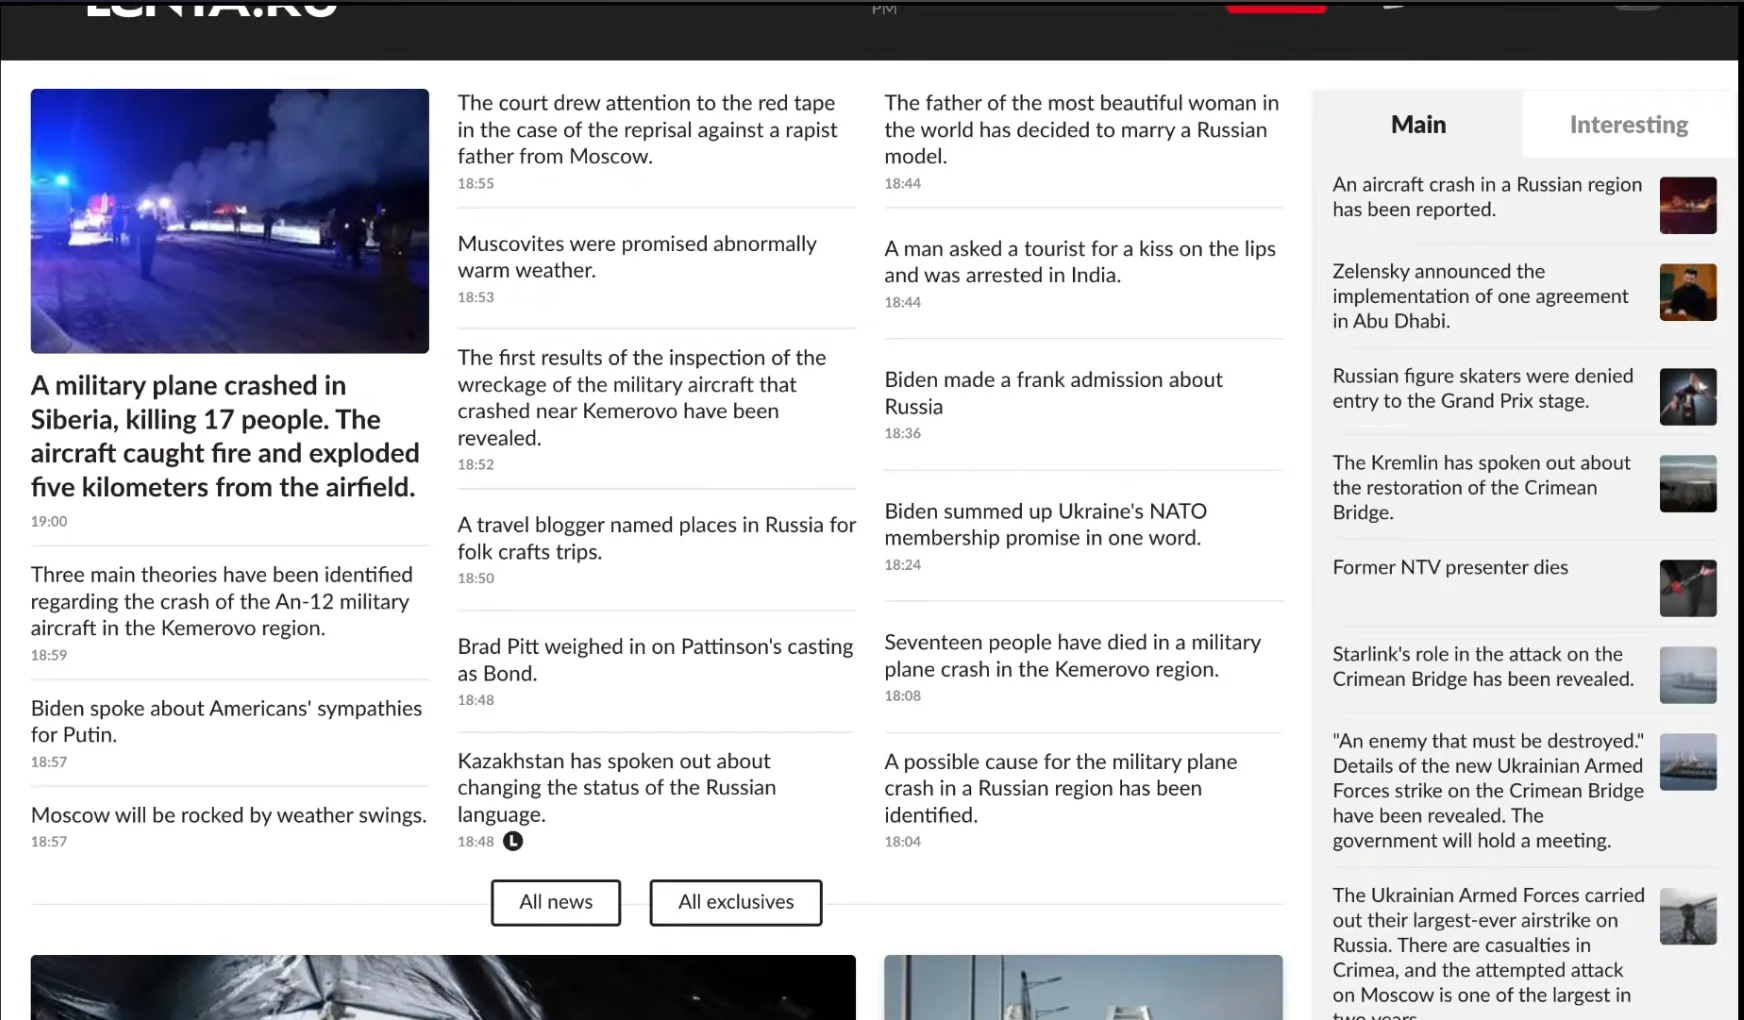
You have to scroll down to find this:
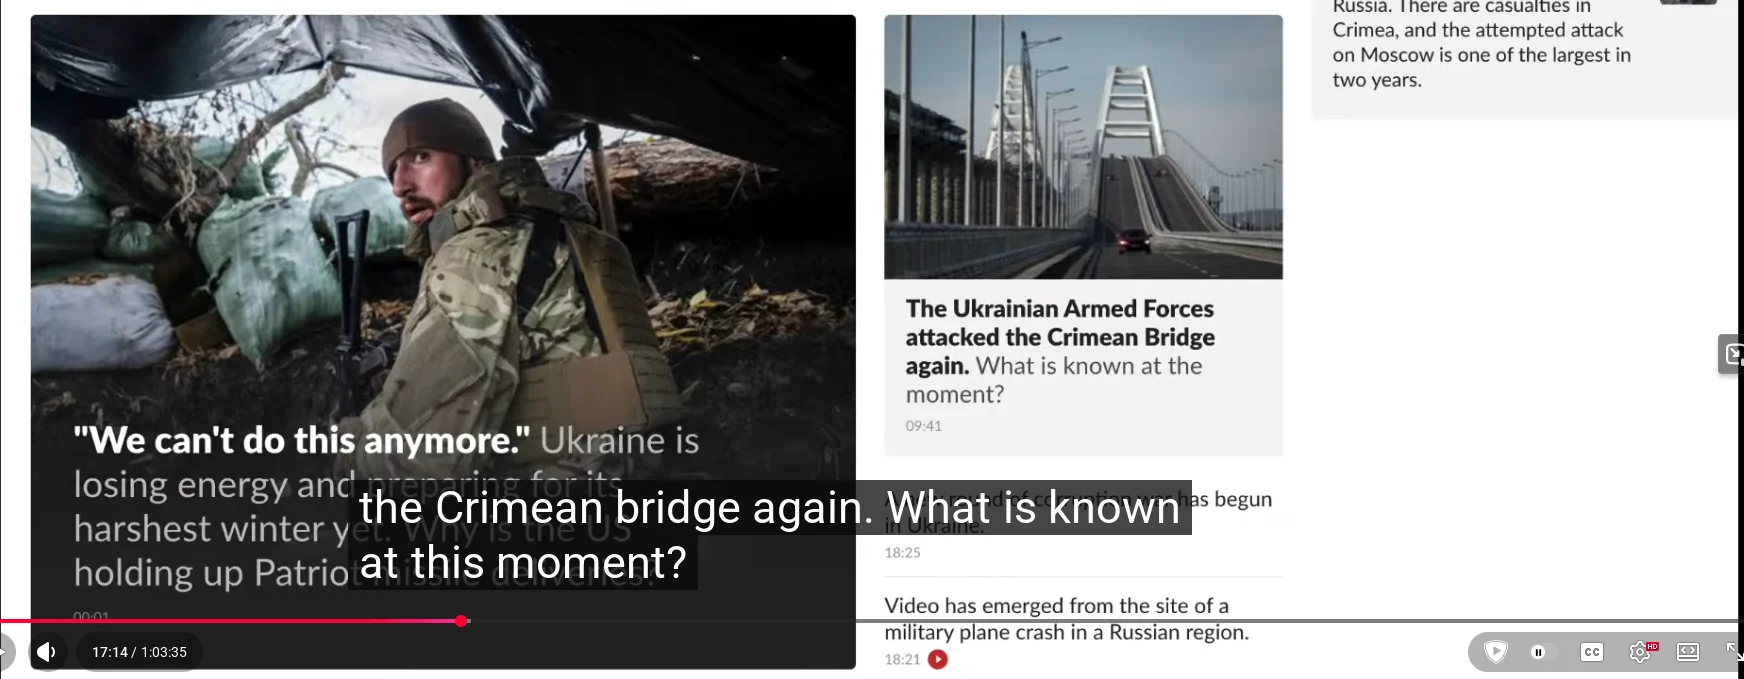
The headlines not even mention that road traffic to Crimea will probably not be re-enabled over Kerch Bridge until the war ends, if ever. They still believe in the military superiority of Russia, and that they are pretty much untouchable. Biden was mentioned 2 times before even acknowledging that there was an attack on Kerch Bridge, and there’s no mention of the damage that cripples logistics towards Crimea and the southern front. Even the picture still shows the bridge intact.
THIS is what propaganda in Russia looks like. Exaggerate wins regardless of their existence, make losses look like things that can be fixed by a task group. Very USSR.
And that’s why for this assault they simply used a mesh network, completely independent from the Muskrat and the Traitor.
Software based solutions will always have the advantage of being applicable to older hardware (maybe with a compatibility layer, but nontheless still viable). Something that should be up-to-date pretty much every day if we apply it to things like internet search simply cannot be solved in hardware alone.
As i said, there are applications where a hardware-based approach is completely valid (like on a production line where nothing essential changes during the time where it is doing stuff), but for other approaches we would be fucked from here to Uranus if we solved everything in hardware.
Ey, Grok is a lot more socially liberal and not nazi than Musk! Alcohol is nice, but no amount of booze can make me forget that there is this inflamed tumor full of pus and rotten blood on the ass of the US called Musk.
They fit the functional criterion of an intelligent system if you cut out the whole process of bringing real innovation instead of applying previous approaches to a wide variety of subjects. As i said, this isn’t nothing, it’s very useful. But it has already been shown that transformer models utterly fail at creating anything resembling original research, which is where intelligence really gets going. This is NOT REPLICABLE by current systems, and will never be unless humans find a new mechanism to enable it - the self-improvement of transformer models is visibly not happening (very much the opposite - too much synthetic data leads to model collapse. Haven’t heard yet of human intelligence collapsing because of more human input) (Edit: this is because LLM-derived training data only enforces already existing pathways through the statistical sieve LLMs are, it cannot create new pathways and actually reduces the capabilities of these models because other valid pathways are getting de-incentivized.)
And a lot of this part of intelligence where humans break previous boundaries is bound to those “nonfunctional mental characteristics” you mention - may it be experiences that cause people to think a certain way that enables these advancements, or emotions that let them follow approaches that are less promising at first glance than the average, but appealing to this individual because of previous experiences. These characteristics are what enable people at the frontier of human knowledge to expand this knowledge.
If given enough time, humans would have solved these mathematical problems on their own, we just take longer to traverse the space of already existing approaches to apply them, because we are not machines (and i heavily suspect OpenAI of simply stealing the approaches used in the cited case). But for real intelligence, we must be able to discard previous assumptions. Even if we take away everything else, LLMs are utterly incapable of escaping their training material, and this training material misses a whole lot of what actually encompasses intelligence.
Another Edit, because i am someone who really thinks iteratively, going over my arguments again and again, refining them as i go over them again - thats part of intelligence too (and another thing that will never become replicated with the current technology used, because it would only lead to model collapse): one of the most important part of intelligence that is completely missing in training data is the refusal to do something (outside of static filters) because the premise is faulty or the available data isn’t enough to reach a solution. These things will try to come to a conclusion by brute force, and the option of “i do not know enough” does never ever come up. This acknowledgement of missing parts in training data // knowledge is what drives humans to fill these gaps, and without an LLM that actively says:“I do not know fuck about this, i need to consult external sources or even do original research” (which as i said, they are incapable of) these things are the illusion of intelligence, but not the real thing.
Source for the inability of LLMs to do original research: https://arxiv.org/html/2601.03315v1 - This study actually provides full information about inputs, artifacts and outputs. I cite: “From these attempts, we document six recurring failure modes: bias toward training data defaults, implementation drift under execution pressure, memory and context degradation across long-horizon tasks, overexcitement that declares success despite obvious failures, insufficient domain intelligence, and weak scientific taste in experimental design.” To be fair, one of those studies was actually fine at the end - but a dataset of 4 studies showing a 25% success rate is not an attractive proposition at all, the real value could plummet very hard compared to 2/4 or 3/4, which i would expect from an really intelligent system.
Edit to my edit (damn this thing is getting long): Of these failure modes i can only see possible improvement in the areas of memory and context degradation. Execution pressure will always be a thing, overexcitement is baked inzo these models by only allowing positive responses into the training data - refusals or proposition for change are not part of this data. Insufficient domain intelligence is the part about “i do not fucking know” which is completely pruned out of LLMs, weak scientific taste in experimental design is an unavoidable issue when using LLMs that can’t step away from training data defaults.
I really have to add one more thing: These studies were things that were doable completely digital, no real world experimentation needed at all. As soon as the real world comes in, i postulate a horrendous decline in usable results, because these systems do neither have real intelligence, nor an “world model” as proposed by the other poster.
2008 had a lot less of direct US Executive corruption - the US execs did not directly try to enrich themselves (or at least not do it blatantly). Compare that to that: https://www.youtube.com/watch?v=W4PIkmjwGsQ (Coffeezilla - 1 hour of analyzing the Trump Clan Crypto schemes, taking bribes from foreign states and industry - he even says that this pretty much only scratches the surface)
Yes, 2008 should not have happened with working oversight by the US Government, and it probably showed up the flaws in the system to these grifters. But what happened in 2008 was not because of direct initiative of the US Gov, unlike now.

Many years ago, one of my cats was able to steal a whole stack of salami from the breakfast table when we didn’t look, biting into the edge of the slices and strutting away with them while they flopped back and forth under her head in rhythm with her steps - she looked so happy, her whole body language was that of “this is fucking awesome and i am the very best hunter around”.
We had to take away 90% from her tho - i do not think close to 200 grams of salami are appropiate nutrition for cats. She very much disliked that :-/
She’s long gone now, but i will always remember her high spirits after this heist.
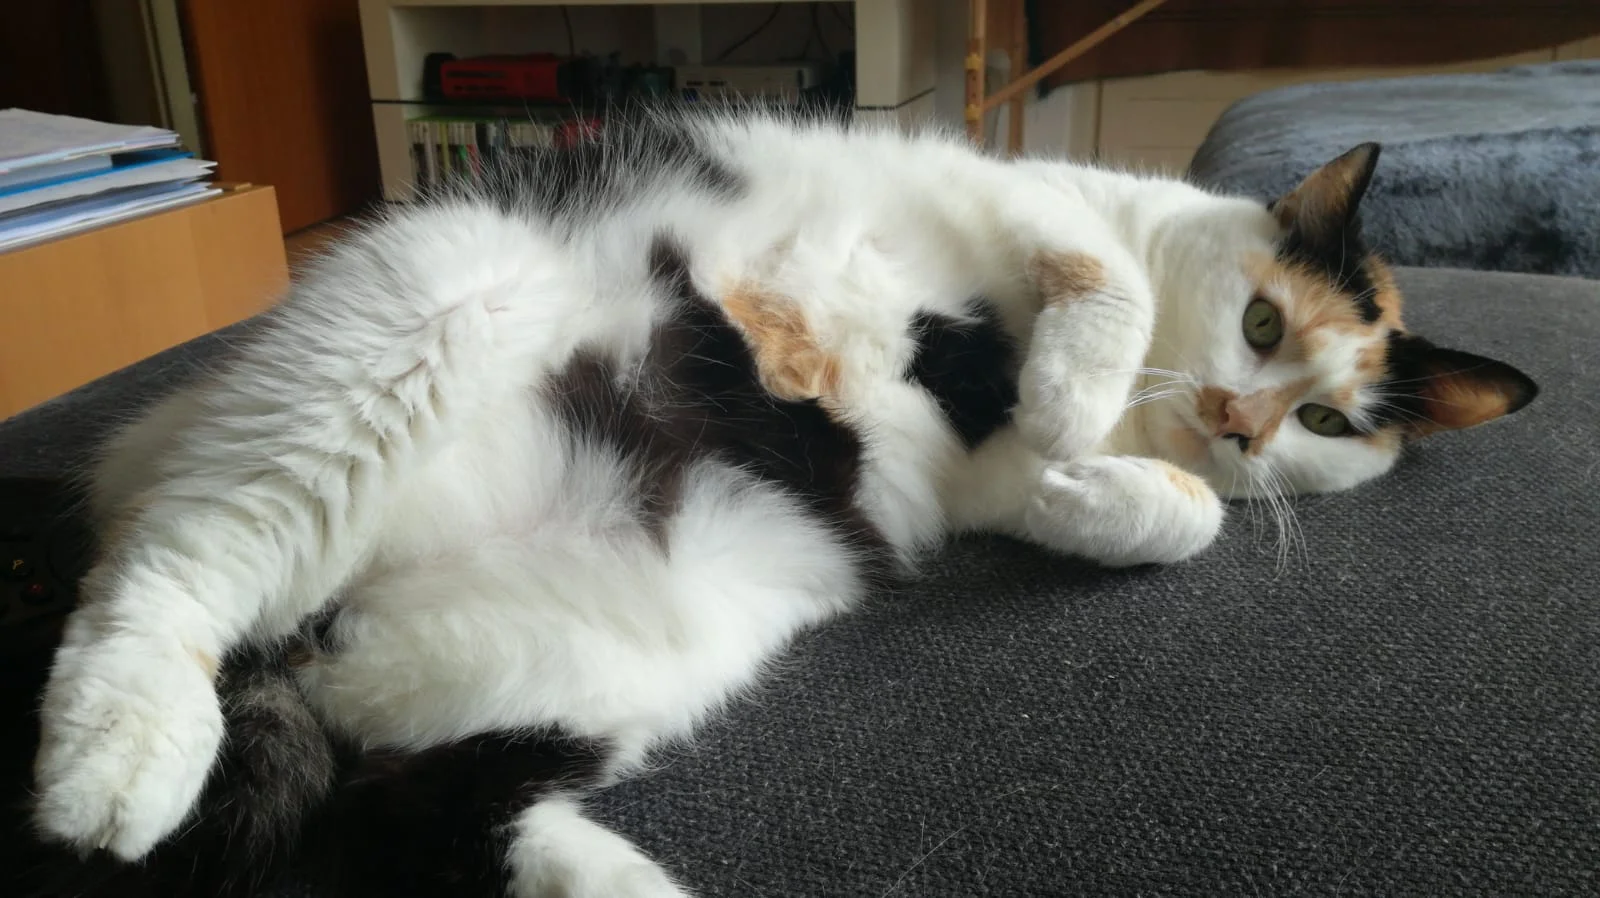
Edit: Damn, I miss her and her brother a lot - he died of cancer 2 years before she died of old age. They were the sweetest cats i ever had (no shade on my current ones tho, they are simply different, not lesser) - both very cuddly, loving every human coming around, having their quirks and whatnot, but always being very approachable even for strangers.
This was pretty much inevitable - there is so much insecure code out there from practically every era of computing. There’s only one answer, and that is giving developers and security experts the resources (that includes LLMs) and time they need to ensure that all this legacy code is being fixed or replaced with better structured code that is less attackable.
It will be a wild ride for a while, and then things will slow down again when the well of not-yet-discovered exploitable bugs starts to run dry.
It’s probably a case of “If they hamstring my defense, at least get some good offense in to demonstrate that these tactics make things worse rather than better”.
UA has been targeting a lot of critical production facilities in the last weeks, including rubber production and chemical plants providing important inputs for the russian military-industrial complex. Fixing these plants while under sanctions and brain-drained (because of either people dying on the front or fleeing before they get drafted) will be a herculean - and very expensive - tasks; smuggling factory parts is both not easy and will come at an pretty insane markup, while russias budget is currently only being propped up by the high oil price and running an insane deficit (and that are the “official” numbers which are sugarcoated). They are currently firing around 40% of all civil servants across the country, and salaries are being delayed more and more - even the christmas bonus for soldiers was delayed (for the first time in the last 2 decades!); they say that it will get paid out next year, to not burden this years budget any more, but i believe it when i see it. There are teachers in more rural areas that have gone without getting their salary for months now according to the “Inside Russia” - Youtube Channel, which is a very grounded and non-sensationalist channel by an exiled russian economist.
For offensive Ops UA is already mostly independent from Starlink/shield, since it doesn’t work over russian territory (and the occupied regions). The throttling mainly hits defensive operations, especially interception of Geran drones.
If anything, this makes UA go all out on wrecking shit in Russia - if you can’t defend yourself reliably, you want to at least deal more damage than the enemy.
We could just replace him with Grok. It would be a net positive.
This is not a “new approach”, it’s the same one but hardware-based. It also is wildly impractical. Models are only useful if they stay somewhat up to date. This way only produces a whole load of garbage everytime you want to update it. Probably useful in the industry or robotics, but not for an everyday LLM.
Intelligence needs something to anchor it in the real world, or it becomes useless. In the biological world, that is a world model, based on previous experiences - and this experience needs at least a modicum of sentience to become useful as we can see all around us. Animals more aware of their own existence are also those who are a lot better at intelligent behavior.
The “intelligent” output we get from LLMs are NOT a sign of intelligence, it is a statistic. This is useful, no doubt about it - having computers that are able to output the average answer one would get if asking someone who knows their shit is a very good thing, as is being able to walk across a large amount of different (pre-existing) approaches. But conflating it with actual intelligence which would be able to correct hallucinations before they are uttered (because the hallucination isn’t logical at all in most cases) and which would be resistant against breaking them by asking them to do irrational things is not the way to go.
There is no representation of the huge amount of rejections to answer a question or do a task that many people are not qualified to work on at all. An actually intelligent being realizes when it reaches the limits of it’s knowledge (or it’s training data). Intelligent beings can then try to extrapolate from existing knowledge, but they know that they actually do not know, and often communicate that (putting social things aside for the moment).
This is the point where LLMs break down with 100% chance if pushed - they do not say: “i do not know”, or “i do not have enough data for that”, or “that doesn’t make sense”. An output is obligatory, regardless of how much an intelligent being would say “oh well, what you want from me doesn’t make sense at all”.
And it’s as easy as asking an LLM to modify their way of communicating: If you tell it to use a symbol/word again after that same symbol/word, and continue to ask it to do this every time it fails to do so (under the guise of having reading or hearing issues) will break these things every time, sending them spiraling. An intelligent being would say “You know what, fuck you, you are messing with me”.
This is actual proof of a complete lack of anything resembling real intelligence - intelligence would allow analysis of the situation and detection of unreasonable requests.
Edit: they trained a model they called “Othello-GPT” with championship datasets, containing only valid moves, and tried to make the point that these things have an internal world model by providing it with game states and asking it for a valid move. It still messed up 5% of the time with real world data, meaning there is no consistent reasoning going on here.
Intelligence and Imagination go hand in hand - as does the world model. If you give anyone intelligent a long list of coordinates, which only consists of 1-8 and a-h, they will also only choose out of these coordinates if you ask them to choose something legal, and they will also realize that a legal move has the prerequisite of choosing coordinates touching an enemy coordinate with one of my own chosen coordinates on the far end of the cluster - this does not involve imagining a “real” Othello Board.
Intelligence (and the world model) also implies that at some point the actual realization of the prerequisites for a legal move. These are pretty simple in Othello - actually, getting a computer to choose a correct move was solved decades ago, so we have actual proof that the playing entity does NOT need any kind of world model and therefore intelligence to ensure 100% of moves are correct.
If these things were intelligent (and as i insist on, world model and intelligence go hand in hand), they would be able to simply use the rulebook as training input and provide close to 100% legal moves. I’d like to see THAT paper, but papers with negative results seldom get published. (Sorry btw, i overlooked that they didn’t give it the rulebook - I was thrown off by the information that 2023 models all have the rules for common board games in their basic training data)
I cited your provided study because it is a very good example how research into LLMs is getting sensationalized. They did not even provide the prompting used in this study, so we have NO information about what they actually asked of the model - it’s simply non-available data, while being the actual seed used to get a result. We do not get information about the quality of the moves (which should probably be somewhere in the top 10% choices of possible moves when taking into account that this is championship data). We NEVER see the full actual output. Instead, we see a LLM having a 5% chance of doing random shit when fed with real world data. We are talking about a 8x8 board here, nothing that comes even close to the complexities of reality.
Edit: I just realized that we are also not shown the test cases themselves and the ratio of valid to invalid moves (and split in “not even touching another piece” and “touching, but invalid”), so we are missing the actual probability of making a valid move by random chance for those 2 variants. They only showed the 93% failure rate on an untrained model, which would be “i place a stone at random”. I’d not be surprised that every move made was at least touching another one - edge detection is one of the easier use cases for transformer models.
It’s the same with their mathematical proofs: we are never given the complete picture, only the result. We do not know what was used as training data, we do not know what “external” information was fed to it, we do not know the prompts used, and we do not know how much compute they have thrown at their room full of monkeys and typewriters to get a result.
I know very well what a “world model’” is, please stop trying to undermine my credibility.
If you feed these things thousands of datasets that only consist of a specific set of coordinates, your output will also only consist of these coordinates, which will create the illusion that they actually have knowledge about how an game board looks (as i said, these things are remixers after all). And feeding it a championship data set, where not one invalid move will appear, should ensure at least a close to 100% of valid moves if they were actually able to have an actual internal model of the system they are trying to manipulate. (and in reality, it should choose pretty good moves too, but this was not evaluated at all…).
Their test cases (and the error rates!) were not even “play a game of Othello”, but feeding them gamestates and asking them for a legal move. IMO, this whole setup does not require any form or shape of a world model, and if it actually existed, the error rates would be a ton lower - the championship data will not contain a single invalid move, and the concept of choosing an empty space on the board, touching the other players piece with one of my own ones on the other side of the mass of pieces, is really not a hard one.
I agree that current models will probably have a better performance, but this is NOT because of a better “world model”, but because the statistical sieve has become a lot finer by blowing up the amount of parameters. This approach is valid, until the amount of parameters becomes unhandleable by current hardware, and it also means much higher energy costs for these computations.
Yeah, the holes were already there - and very visible at latest with Nixon getting away without a prison sentence - but until Trump there was at least the notion that personal enrichment of the executive is something you don’t do (or at least be very careful about it).
Sadly, i do not think that in 2029 we will see actual change. The whole basis of the USA, starting with their constitution, is woefully underequipped to deal with wanna-be dictators like Trump, and the “civil religion”-aspect of the USA will probably prevent the enactment of the needed changes to their “holy” scripture. Even if in the short term there’s a swing of the pendulum towards a more just society, i do not believe that the real problems will be getting fixed at that point.

If it’s the only human boner in the world, it really is a sensation!